
AI in governance interview: why India must fix fragmented data before it scales AI
India has built government technology at a scale few countries can match. The Tony Blair Institute argues the next constraint is not more infrastructure but fragmented data — and that AI layered on top of it will amplify existing blind spots rather than fix them. In this AI in governance interview, TBI’s Vivek Agarwal sets out what “good enough” data looks like, and how states should sequence reform before rollout.
Organisation Introduction
The Tony Blair Institute for Global Change is a policy institute that works with governments on delivery and technology. Its paper From Digital Scale to Data Power: A Data Operating Model for India’s States (8 October 2026) examines how fragmented government data affects the cost and delivery of state welfare — and why that matters before states scale up AI.
The report’s argument is deliberately unglamorous. India’s digital public infrastructure is real and works at scale; what it lacks is a cross-government operating model that makes priority data reliably usable across existing systems. Its central claim is that data fragmentation is not an administrative inconvenience but a delivery failure — producing fiscal leakage, exclusion from welfare schemes, and weak accountability.
The paper sets out seven recommendations for states, builds on MoSPI’s initiatives, and draws on working state programmes. This AI in governance interview treats it as a policy argument to be tested rather than a report to be summarised.
Executive Introduction
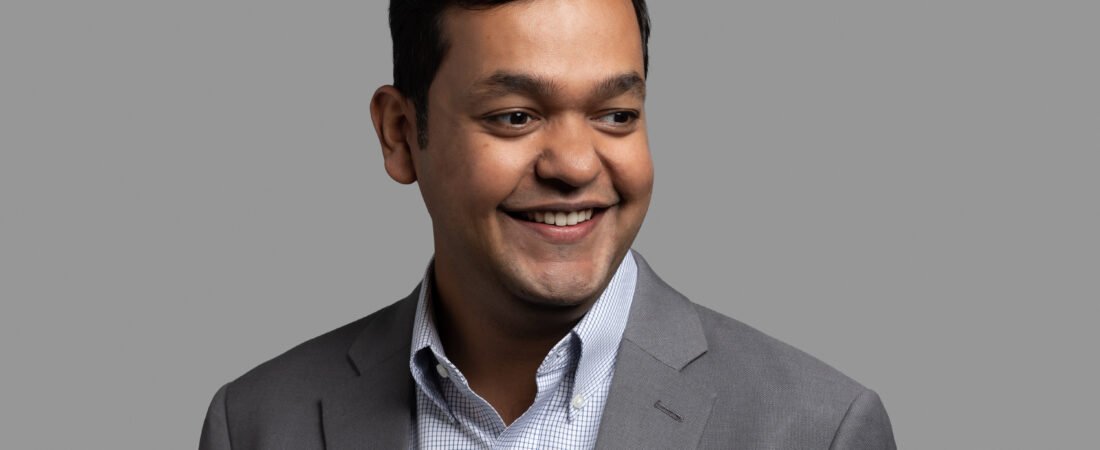
Vivek Agarwal is Country Director at the Tony Blair Institute for Global Change, and the spokesperson for this report.
His subject in this AI in governance interview is sequencing: why the next phase of India’s digital government is a data problem rather than an infrastructure one, and why AI deployed on fragmented data risks scaling errors instead of resolving them. He can speak to which states are closest to being AI-ready, what “good enough” data looks like before an AI system or an official acts on it, and how states should use MoSPI’s harmonisation roadmap in practice.
The report he presents is specific enough to be argued with. It cites NITI Aayog’s 2025 assessment that poor data quality causes fiscal leakage of 4–7% of annual welfare spending; it points to database clean-ups that removed 17.1 million ineligible names from PM-KISAN (an estimated ₹90 billion saved), 35 million bogus LPG connections (₹210 billion over two years), and 16 million fake ration cards (roughly ₹100 billion a year). Readers will come away with a clearer view of where the data actually breaks, what a state data operating model contains, and what has to happen before AI is worth deploying.
The binding constraint
Q1. In one line, why is fragmented government data the real constraint rather than digital infrastructure?
VA: Digital infrastructure is only as good as the data that goes into it. Aadhaar and DBT work at remarkable scale, but data on schemes, projects and outcomes still sits in silos. Linking it would cut leakage, show what works and enable better policy for all. That is PM Modi’s vision of minimum government maximum governance in action.
Q2. How does AI deployed on fragmented data amplify existing blind spots rather than resolve them — mechanically, not rhetorically?
VA: AI models don’t always treat missing or mismatched records as an error. If a household is missing or spelled differently across scripts, the model has nothing to match it to. So it scores people on incomplete variables, learns past exclusions as if they were signals, and repeats them across millions of cases at machine speed. That’s why our report says that benefits shouldn’t be suspended without false-positive testing, official review and a route to appeal.
The fiscal case
Q3. The report cites NITI Aayog’s estimate that poor data quality causes fiscal leakage of 4–7% of annual welfare spending. What does that figure actually measure, and how firm is the estimate?
VA: As I read the analysis, it estimates the share of welfare spending reaching the wrong person or amount because records are duplicate, outdated, mismatched or incomplete. It isn’t an audited loss. I’d treat it as an order-of-magnitude indicator: the range is wide, it’s modelled rather than measured, and it doesn’t separate fraud from honest error. Each state should measure its own figure rather than rely on this one.
Q4. The PM-KISAN, LPG and ration-card clean-ups removed millions of ineligible entries. What do those cases tell you about where data breaks — and what do they not tell you?
VA: They show data breaks at entry and linkage: duplicates, deceased or migrated beneficiaries mismatched names, and land records that don’t reflect reality. They also show the scale large enough to matter. What they don’t show is accuracy. A removal count isn’t proof of ineligibility, and we rarely see how many genuine beneficiaries were dropped. The report itself cites studies, where database errors cut people off from food benefits. Savings are visible; wrongful exclusions mostly aren’t.
Good enough data
Q5. What does “good enough” data look like before an AI system or an official acts on it — what are the minimum properties?
VA: It’s decision-specific, but I’d test for five qualities.
Timely: data is dated and refreshed known schedule.
Reliable: it has a named owner, a documented source and a measured error rate, so an official knows how far to trust it.
Holistic: the fields the decision depends on complete, across schemes rather than one department.
Secure: access is controlled and every use has a lawful basis.
Interoperable: records can be matched across systems and scripts, using common definition.
Q6. How should a state test data quality continuously rather than at a single point in time?
VA: It needs to be treated as two distinct exercises rather than a one-off audit.
The first automated and rule-driven, run by machines at set intervals. Each new data feed is cross-validated against existing records and other systems; the report notes one state’s HMIS recorded 728 infant deaths in a quarter against 3,307 in its surveillance system. Rules also catch duplicates and impossible values, and flag records due to retirement, such as beneficiary who has died, migrated or not drawn a benefit in a set period.
The second manual audit, regular but spaced. Field verification of a sample of records each cycle, run by body outside the departments that publishes its results, so owners are accountable for trends. Grievances and appeals feed both as a live error signal.
The operating model
Q7. Walk us through the seven recommendations. Which is hardest to implement inside a state bureaucracy, and why?
VA: In substance, they ask states to: set up an empowered data office; name owners for the top 20–50 datasets; adopt common standards and identifiers; build shared exchange infrastructure; assure quality through an independent audit body; put legal and procurement safeguards in place; and maintain a State Data Balance Sheet.
The hardest is the data office with power to compel sharing. The report is candid that officials resist sharing because information is power. It means shifting control from departments to a central body, and that is a political negotiation, not a technical task.
Q8. What is a “State Data Balance Sheet” — what does it contain, who maintains it, and what decision does it change?
VA: It’s a register of a state’s data assets, with the liabilities and risks attached: quality gaps, unclear legal basis, security exposure, vendor lock-in and an “AI readiness” rating. Named dataset owners supply the entries; the state data office compiles them, and independent aud should test them. It’s reviewed alongside the budget. The decision it changes is where money goes first: which datasets get cleaned before funding more AI. It’s a prioritisation tool, not guarantee, and it is only as honest as the reporting behind it.
Sequencing Data Reform
Q9. How should a state sequence data reform ahead of AI rollout — what comes first, second and third?
VA: First, authority and accountability: a data office with real powers, named owners for the priority datasets, and a clear legal basis for sharing. Second, quality and linkage: common standards and identifiers, handling of multiple languages and scripts, a baseline audit and the balance sheet. Third, AI itself, starting with lower-stakes, advisory uses, with human review and appeal routes in place before anything touches entitlements. In practice these overlap, but AI shouldn’t lead. MoSPI’s roadmap, with state data bodies by December 2026 and exchanges by December 2028, offers a useful clock.
Q10. Which states are closest to AI-ready, and what specifically distinguishes them — Kutumba, Pehchan, Tamil Nadu’s family database, Odisha’s delivery platform?
VA: Honestly, none is fully there. Karnataka’s Kutumba, Rajasthan’s Pehchan, Tamil Nadu’s family database, Telangana’s data exchange and Odisha’s delivery platform are credible foundations.
What distinguishes them is a shared, household-level record that several departments actually use, plus an administrative mandate behind it. But the report notes they remain largely limited to select sectors. What’s still missing almost everywhere is cross-sector quality assurance, independent audit, and routes for citizens to contest errors.
Putting the thesis to the test
Q11. What would prove the report wrong — is there a case where AI can work usefully on messy data?
VA: Evidence that a state deployed AI on unharmonised data for entitlement decisions and measured lower false-positive and exclusion rates than the manual process it replaced. I’d welcome that. Our argument is about decisions affecting people’s benefits. Plenty works on messy data: translating, summarising, triaging grievances, flagging anomalies for human review, and even entity-matching to help clean records. Where a human checks the output and the stakes of error are low, messy data is tolerable. Where the model decides, it isn’t.
Q12. What is the strongest argument against “fix the data first”, and how do you answer it?
VA: That perfect data never arrives, so waiting becomes an excuse for inaction while citizens go unserved, and AI can itself help clean data. That’s fair, and the risk is real. My answer is that we aren’t asking for perfect data, only data fit for the specific decision, with sequencing by stakes. Use AI to assist clean-up under human review. But errors in welfare decisions fall hardest on people least able to contest them, so the bar should rise with the consequences.
TechRecast Analysis (The Recast)
The Shift in Context
India’s digital public infrastructure phase is largely done: identity, payments and enrolment work at a scale few countries can match. The next constraint is the layer underneath the applications — whether the same citizen is the same record across departments, whether the definition of a household is consistent, whether the data is current. That is a far less visible problem than a new platform, and it is where this AI in governance interview sits.
Why This Interview Matters
Most AI-in-government commentary is about procurement or pilots. This is about the substrate those pilots depend on: if the underlying records are fragmented or stale, an AI system does not fix the error, it propagates it at machine speed and with apparent authority. That reframing is what makes the sequencing argument worth taking seriously.
Technology Perspective
The technical crux is interoperability across four dimensions — technical, semantic, organisational and legal — and the semantic layer is the hardest, because it is where definitions diverge. A system can exchange records perfectly and still be wrong if “household” means different things in two departments. The report’s insistence on authoritative sources, stewardship and independent quality assurance is really an argument about the semantic and organisational layers.
Business and Market Perspective
The fiscal argument is the persuasive one: leakage at 4–7% of welfare spending, and clean-ups that recovered large sums simply by linking existing siloed records. The honest caveat, which the report itself makes, is that these are gross savings — the exclusion and correction costs sit on the other side of the ledger.
Leadership Perspective
The institutional position — a delivery-focused institute working with state governments — shapes the argument toward what a state can actually implement, rather than what a national policy could mandate. The relevant lens is whether the seven recommendations survive contact with how state bureaucracies allocate authority.
The Counterpoint
A fair sceptic would argue that “fix the data first” is a recipe for indefinite delay, that AI pilots have produced real value on imperfect data, and that the sequencing argument conveniently protects incumbents. On this view, the report risks setting a standard that no state can meet before it is allowed to start. This is the strongest opposing case and deserves a direct answer.
What Comes Next
Watch three signals: whether states meet the December 2026 milestones (a governance body, data inventories, named custodians), whether any state publishes a State Data Balance Sheet in practice, and whether AI deployments are assessed against a defined use case rather than a general “readiness” claim.
Industry Outlook
If the report is right, the next phase of Indian digital government is unglamorous integration work, and AI adoption follows rather than leads. If it is wrong, states press ahead with AI on imperfect data, and the cost shows up as exclusion errors and misdirected spending rather than as failed pilots.
Key Takeaways
1. India’s digital infrastructure is built; the constraint is now cross-government data, not more platforms.
2. Fragmented data is a delivery failure — fiscal leakage, exclusion and weak accountability — not an administrative inconvenience.
3. NITI Aayog’s 2025 assessment puts leakage from poor data quality at 4–7% of annual welfare spending.
4. Clean-ups that merely linked siloed records recovered large sums, which shows how much of the problem is linkage rather than collection.
5. “Good enough” data should be defined against a specific use case, not as a general readiness claim.
6. The strongest counter-argument is that “fix data first” can become indefinite delay, and pilots have produced value on imperfect data.